Chat and models
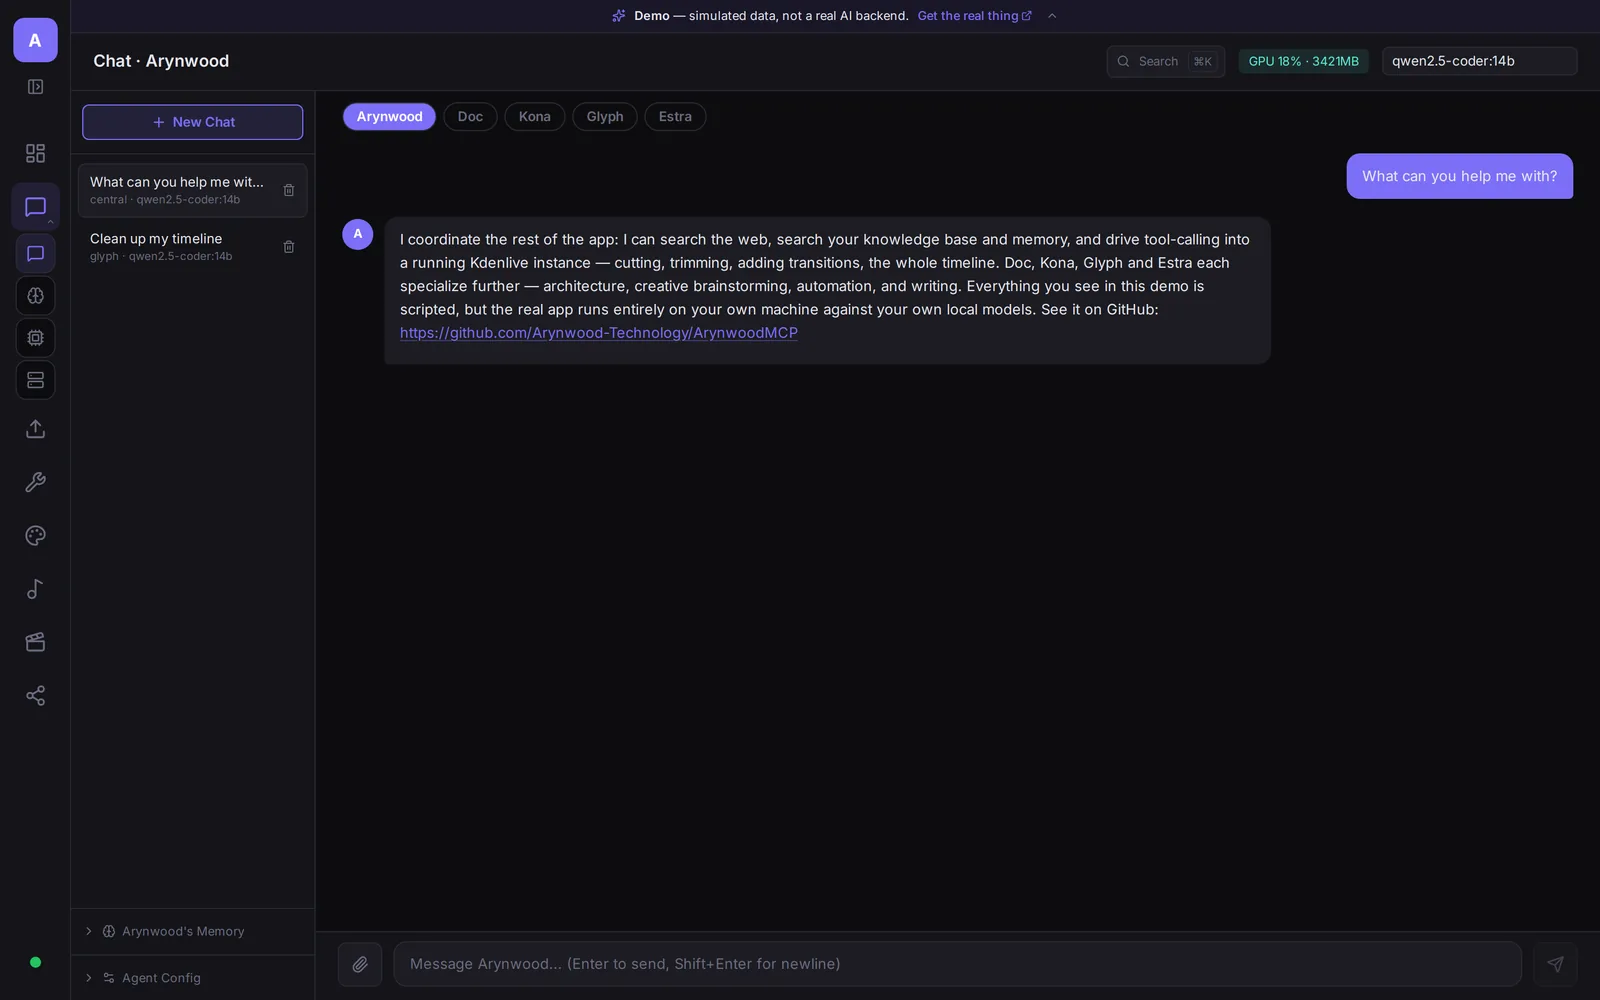
Multi-persona chat that streams from Ollama. Browse, pull and delete models, and register local or remote Ollama and OpenAI-compatible servers.

Personal AI · Linux desktop alpha
A local-first AI workspace for the Linux desktop. Chat with your own models, search your documents and connect creative tools, all against your local Ollama.
What’s inside
Start with Ollama chat, then add the services your workflow needs. Models and supporting services are installed separately.
Multi-persona chat that streams from Ollama. Browse, pull and delete models, and register local or remote Ollama and OpenAI-compatible servers.
Teach it from a URL, a file or pasted text, then search your own documents. Uses Qdrant and an Ollama embedding model.
A canvas design tool. Image generation connects to a separately installed A1111 service.
Optional music and audio tools through separately installed MusicStudio sidecars.
Model Context Protocol tool servers, including Kdenlive editing through Cutroom’s MCP server. Each tool server is configured separately.
A Ctrl+K command palette and a system status drawer on every screen, with live service health on the dashboard.
Requirements
From the v0.4.3 documentation. Read the versioned platform requirements.
| Operating system | Linux x86_64. AppImage or Debian/Ubuntu .deb. Windows and macOS are not supported. |
|---|---|
| Memory | 16 GB RAM minimum in the project documentation. Model size affects memory use. |
| Storage | At least 20 GB free, plus space for models and generated media. |
| Chat GPU | Optional. Ollama can run chat on a CPU, more slowly. See measured CPU speeds. |
| Creative GPU tools | An NVIDIA GPU for the documented GPU services. At least 12 GB VRAM is the project’s practical recommendation. |
Get started
Get chat working first, then add knowledge search and creative tools one at a time.
Step 01
Get the x86_64 AppImage or .deb from the v0.4.3 release and check it against SHA256SUMS.txt. Make the AppImage executable, or install the .deb with its GStreamer packages.
Step 02
Ollama isn’t bundled. Install it, then pull a model that fits your RAM or GPU memory. A 3B model is comfortable on a CPU alone.
Step 03
Pick the model and send a message. Once that works, add Qdrant and an embedding model for knowledge search, then any creative services.
curl -fsSL https://ollama.com/install.sh | sh
ollama pull llama3.2:3bQuestions
What it includes, what it needs, and what stays on your machine.
No. The download contains the interface and backend. Ollama and its models are installed separately, and so are Qdrant, A1111 and MusicStudio if you use those features.
Yes. The browser demo runs the real interface with scripted conversations. It is not a live AI; features that need a GPU or backend say so.
Chat can run on a CPU through Ollama. On a 2012 8-core Xeon with no GPU, a 3B model generated about 13 tokens per second, faster than most people read. See the full CPU benchmark. GPU generation features have separate NVIDIA requirements.
Its source code is public on GitHub under the Arynwood MCP Source-Available License, which is not an open-source license. Read the LICENSE file for what it allows.
Local models run on your hardware. Downloads, web search, remote endpoints and social publishing use the network. Local-first describes a deployment choice, not a promise that every feature works offline.
Keep reading
Benchmark · Ollama
Three Ollama models measured CPU-only and on an RTX 3060, on a 2012 Xeon workstation.
Read the benchmarkSetup guide · v0.4.3
Hardware requirements, install steps and what the packaged alpha includes.
Read the guideVideo · Kdenlive
An AI-assisted video editor built on Kdenlive, with an MCP server Arynwood MCP can drive.
Meet CutroomLocal AI setup & integration
Tell me your Linux distribution, hardware and the task you want AI to help with. I’ll scope a paid setup around your machine.